min to x_max
modeled below min, never observed
censored beyond the ceiling
data floor min
ceiling x_max
Fitted curve — real log2 units, each gene on its own
scale. Shows what was fit; cells are not comparable to each other.
Curve coverage — every gene on one −4σ … +4σ ruler.
Solid band = how much of the fitted curve the data actually spans, so a sliver
means σ dwarfs the data. Ceiling sits at σ-dist.
RTI = f(x_max)/f(peak) · oldLTI = f(x_min)/f(peak), baseline
removed from both. Only one is ever non-zero — the baseline is whichever
edge sits farther from the peak, so that side reads 0.
min to x_max
modeled below min, never observed
censored beyond the ceiling
Same fit, same columns, same two shape cells as the
human tables — one C. elegans dataset rather than 54 tissues,
so there is nothing to select and the whole table loads at once.
What this project is asking
Some genes are dosage-sensitive: the cell needs the amount of their product to stay inside a window. For some, too much is harmful (triplosensitivity); for others, too little is (haploinsufficiency). Those genes are enriched among the causes of developmental disorders, and they are the ones where a duplication or a deletion is most likely to matter.
Why look at healthy people
The usual way to find a dosage-sensitive gene is to study patients who have a disorder. This project asks the opposite question: what can you learn from people who are fine?
If expressing too much of a gene is harmful, then among healthy people you should not find anyone expressing it past some ceiling — those individuals are not in the cohort. The gene's expression distribution across the population is then truncated: the upper tail a normal distribution would predict is missing. The same logic runs downward for a gene where too little is harmful, cutting off the lower tail instead.
So a constraint that would normally be studied through disease leaves a footprint in a healthy population — a distribution with an edge where a tail should be. The truncation index is an attempt to measure that edge.
The data
GTEx v11: bulk RNA-seq across
54 human tissues, one expression value per gene per
donor, transformed to log2(TPM + 1) − 1. Donor counts range
from 11 (kidney medulla) to 818 (skeletal muscle), and that range turns
out to govern almost everything below.
GTEx donors are deceased organ donors — people without the disorder in question, not a screened healthy cohort. "Healthy" here means "not selected against by whatever the gene does", which is the assumption the whole method rests on.
The measurement
Each gene's expression histogram (40 bins) gets a 4-parameter Gaussian fit. The index then asks how high the fitted curve still is where the observed data stops:
- RTI —
f(x_max) / f(peak). The right, or upper, edge. The overexpression-is-harmful side. - oldLTI —
f(x_min) / f(peak). The left, or lower, edge. The haploinsufficiency side. - LTI — oldLTI, set to 0 wherever the gene's lowest detected value is at the detection floor, since there the lower edge is the assay's limit rather than biology.
Both are bounded [0, 1]; higher means the edge cuts closer to the peak, so more of the distribution is missing. The two σ-distance columns are the same geometry expressed in standard deviations instead.
The two sides share a baseline — the curve's minimum across the observed range — which is whichever edge sits farther from the peak. That edge therefore reads exactly 0, so only one of RTI and oldLTI is non-zero for any given gene. They name which side is closer; they are not two independent measurements.
Approaches
- 4-parameter Gaussian on the histogram — fast, but biased by construction, because it is fit to data that is already truncated.
- Truncated-Gaussian MLE on the raw values — slower, but models the missing tail explicitly, so it recovers the distribution the population would have had.
- A distribution-classification cascade that rules out zero-inflation, multimodality and ordinary skew before anything is called truncated, with thresholds calibrated against simulated null data rather than textbook constants.
- Control gene sets — known dosage-sensitive genes (pTriplo, DECIPHER dominant) scored against genes that tolerate extra copies (duplication-tolerant, olfactory receptors).
What has actually come out of it so far
Read this before treating any candidate list as biology.
- Power is the binding constraint. At ~100 donors, a ceiling 2–3σ out from the peak removes too little of the distribution to see. 20 of the 54 tissues have fewer than 200 donors, so a null result there means "underpowered", not "no truncation".
- The one real excess is probably an artifact. In skeletal muscle (n = 818) the rate of truncated-looking genes runs about 3× the calibrated null. But the genes are that tissue's own highly-expressed identity markers, sitting at the 92nd–93rd percentile of expression, and the candidate lists from two tissues do not overlap at all. Donor-to-donor differences in tissue composition and RNA quality produce exactly that pattern, and are indistinguishable from a real expression ceiling by this statistic.
- The index tracks expression level. Once control genes are matched on expression, the signal has so far been at chance.
- oldLTI has its own version of that problem. The lower edge of the data is also the detection floor, so a gene that is barely expressed looks left-truncated for purely technical reasons. LTI zeroes the genes that sit on the floor, but still read it beside mean expression, never alone.
This is a method under test, not a finished result. The browser exists so the numbers can be inspected gene by gene rather than taken on trust.
Worms
The truncation index was developed and applied in C. elegans by Swetha Iyer and Sophie Sanchez in the Pierce Lab, which is where this project starts from. The Worm data tab carries that dataset — 25,849 transcripts, fit the same way over the same 40 bins, so every column means what it means for a human tissue.
A worm is a useful counterpart to GTEx: the animals are near-isogenic and reared in a controlled environment, so a truncated distribution there is much harder to explain away as sample heterogeneity.
People
This work is carried out in the Pierce Lab at The University of Texas at Austin.
-
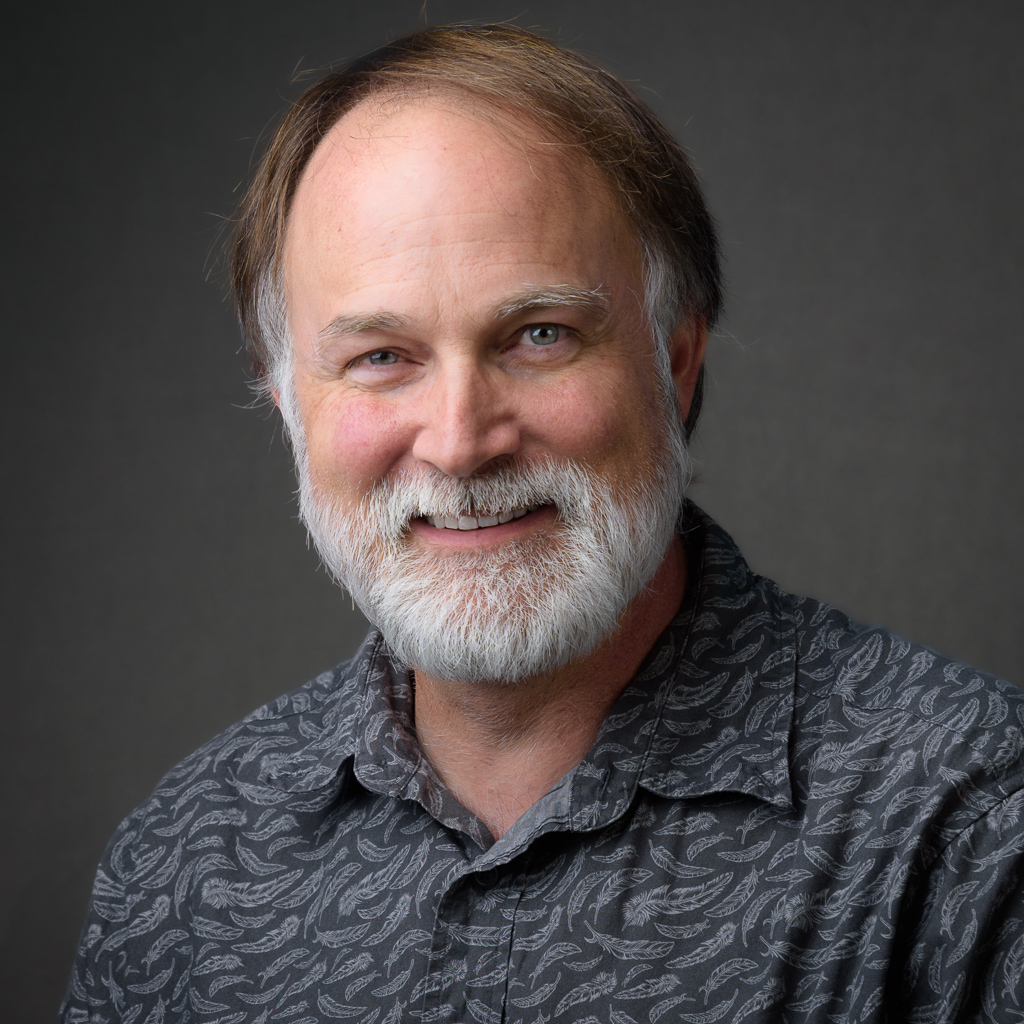
Dr. Jon Pierce
Principal Investigator
Leads the Pierce Lab, which uses C. elegans to investigate the genetic mechanisms behind behavior and neurological disorders.
-
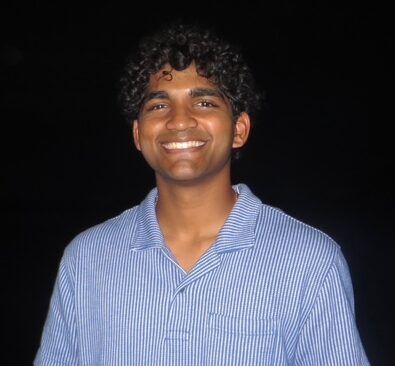
Bhuvan Kanna
Creator
Built the truncation-index pipeline and this browser: the distribution fitting, the per-gene metrics across all 54 GTEx tissues, and the interface for reading them.
More lab members to be added.
—
Looking up gene description…